Hybrid Movie Recommender System in Neo4j
Built a hybrid Neo4j movie recommender modeling users, movies, genres, and directors, combining Jaccard collaborative filtering with FastRP embeddings and Precision@K evaluation.
Role
Data Analyst
Category
Recommender Systems
Year
2026
Deliverables
Enriched Neo4j graph, hybrid scoring engine, hold-out evaluation
20%
Rating density (sparse graph)
94%
Ratings are 4–5 stars
1.0
Precision@10 on hold-out test
4
Node types in enriched graph
The problem
Streaming platforms have a discovery problem: collaborative filtering fails on cold-start users, and content-based filtering fails when rating data is sparse. This project builds a hybrid Neo4j recommender that reasons over users, ratings, genres, and directors in one connected graph.
The dataset — 20 users, 25 movies, 100 ratings (~20% density) — is intentionally small. That sparsity makes the hybrid design necessary rather than optional.
Graph design
Raw CSV import creates a bipartite User–Movie graph via RATED relationships. Content-based and hybrid scoring need more structure, so I materialised:
- Genre nodes linked via
IN_GENRE - Director nodes linked via
DIRECTED_BY
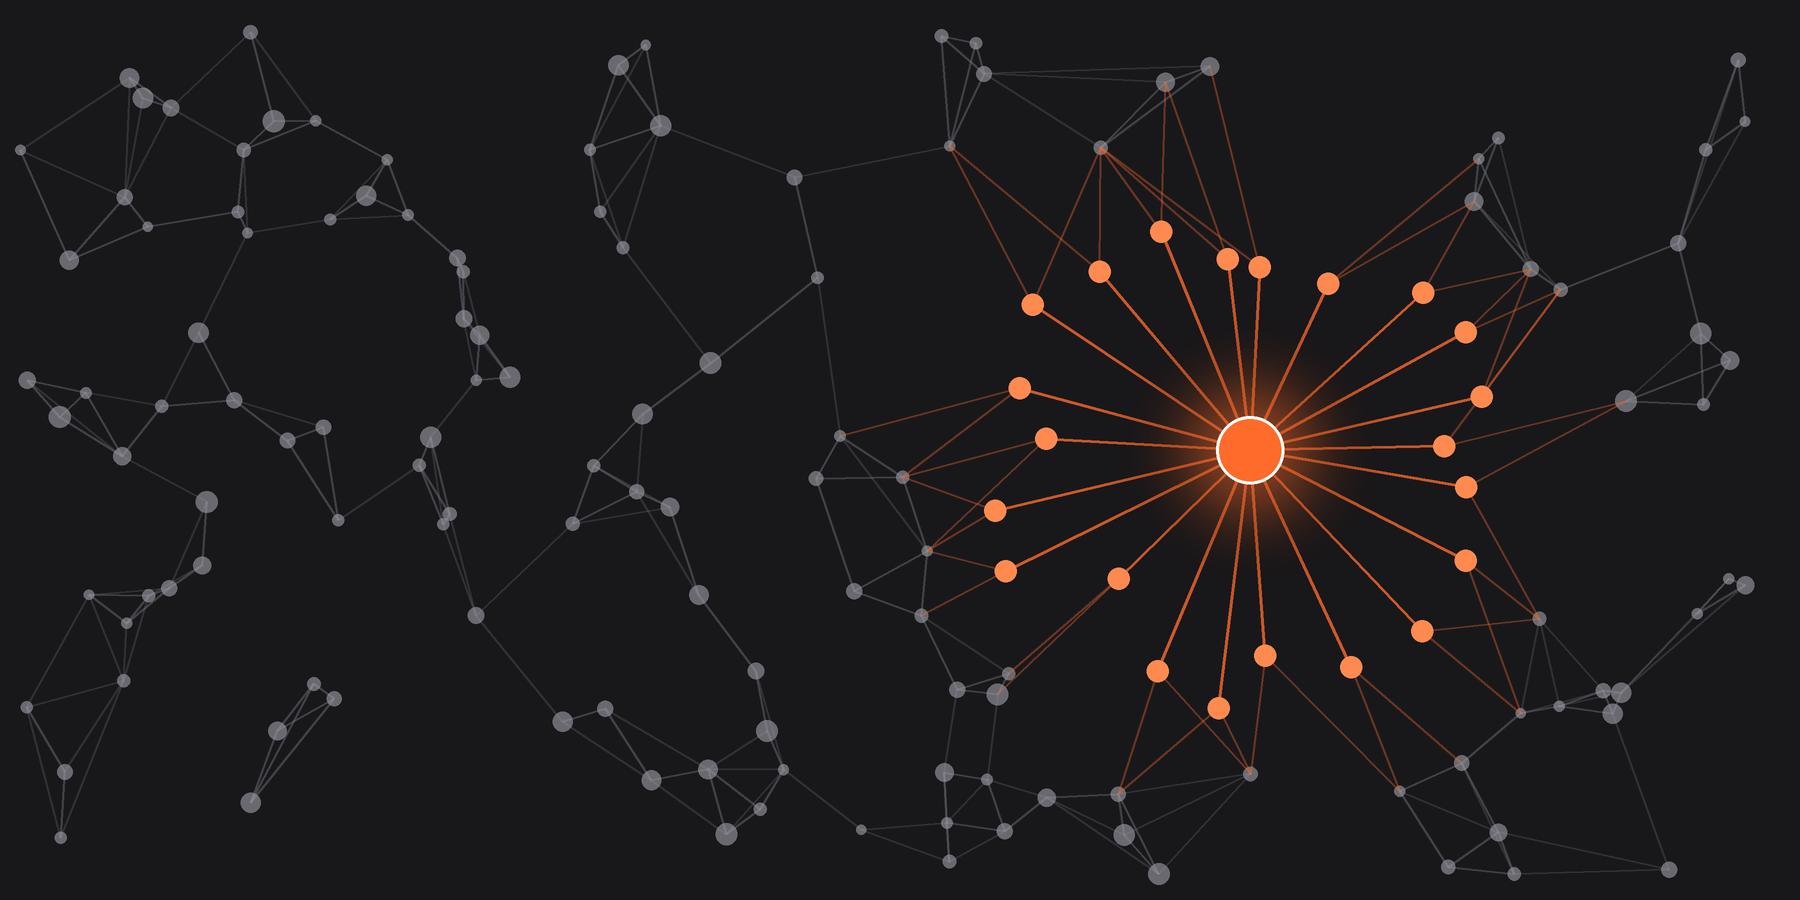
That enrichment lets FastRP propagate preference signals through structural paths that pure co-rating overlap cannot reach — especially for cold-start users.
What EDA forced into the design
- Rating inflation: no 1–2 star ratings exist; 94% of ratings are 4 or 5. A "3" effectively functions as a negative signal.
- Scale mismatch: user ratings are 1–5 while movie
avgRatingis 1–10 — comparisons require normalization. - Sparsity: collaborative filtering alone becomes popularity-biased quickly.
Hybrid scoring engine
I combined three signals:
- Jaccard unweighted similarity (
SIMILAR_TASTE) for collaborative filtering - FastRP embeddings + kNN cosine (
KNN_SIMILAR) for structural/content similarity - Explicit genre and director bonuses for content relevance
Louvain community detection on the user similarity graph produced taste clusters that aligned with genre preferences, validating that the enriched graph captures real structure.
Key finding
Combining collaborative and content-based signals in one graph solves sparsity and cold-start where either approach alone fails. Graph enrichment is essential — not optional.
Evaluation
On a directional hold-out test, both held-out films (Dune, Blade Runner 2049) appeared in the top 10 — Precision@10 = 1.0. That result is illustrative, not statistically conclusive: a production pipeline would need k-fold cross-validation with precision@k, recall@k, and NDCG across all users.
Sensitivity analysis on Jaccard cutoffs (0.1 / 0.3 / 0.5) showed that sparse graphs need lower thresholds — discarding scarce collaborative signal isolates users.
Interested in similar work? Get in touch.