When Poisson beats OLS: modeling count data the right way
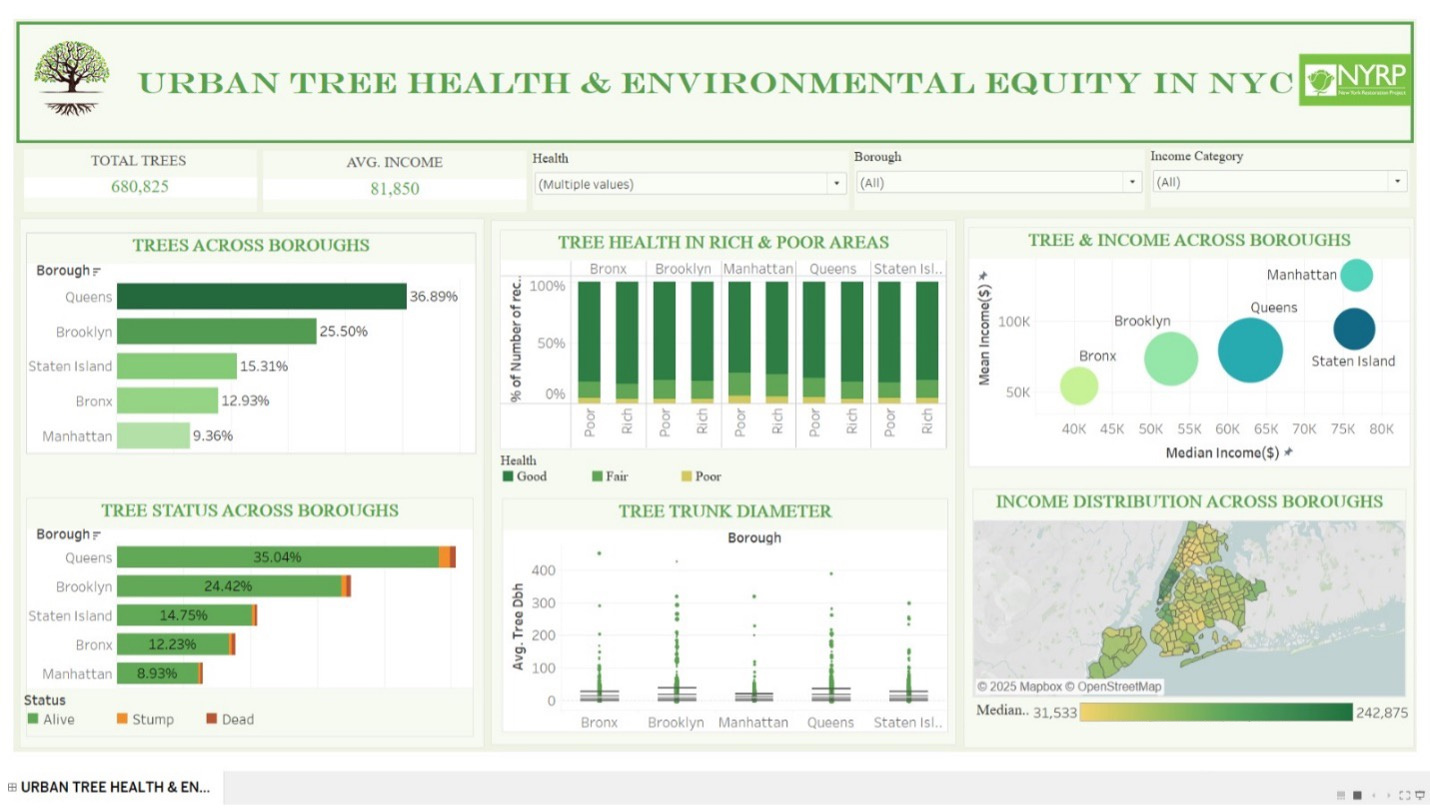
On 39,674 NYSED records (140 variables), migrant and ELL students face 3× higher dropout rates, NYC averages 13.2% vs 7.5% elsewhere, and enrollment size is the strongest driver.
Arnold Muzarurwi
Data Analyst candidate
Counts are not continuous
Student dropout counts per district are non-negative integers with variance that scales with the mean. OLS assumes continuous, roughly homoscedastic errors — assumptions that break immediately on NYSED count data.
I analyzed 39,674 school district records across 140 variables, cleaned privacy-suppressed fields, removed multicollinearity, and validated findings with cross-validated statistical models.
What the data showed first
- Migrant students and English language learners face over 3× higher dropout rates
- NYC districts average 13.2% dropout versus 7.5% elsewhere
- Enrollment size is the strongest driver of dropout volume
The metric trap
OLS on the log dropout rate can post a tiny RMSE on a transformed scale while failing the actual task of predicting raw dropout_cnt. Comparing that to Poisson RMSE ≈ 14.97 is apples to oranges.
For count prediction, only count-scale metrics are comparable. Transformed-target models need honest conversion back to counts before they enter the bake-off.
What actually won
Among models that predict dropout_cnt directly, Poisson P2 won — categorical context, numeric covariates, county fixed effects, and a log(enroll_cnt) exposure offset (test RMSE ≈ 14.97, MAE ≈ 5.52).
The stakeholder story and the model story agree: enrollment, geography, and subgroup risk are the levers — once the model family matches the data type.
Want to discuss this work? Get in touch.